Where data lives
On your hardware
Prompts, files, and outputs stay local.
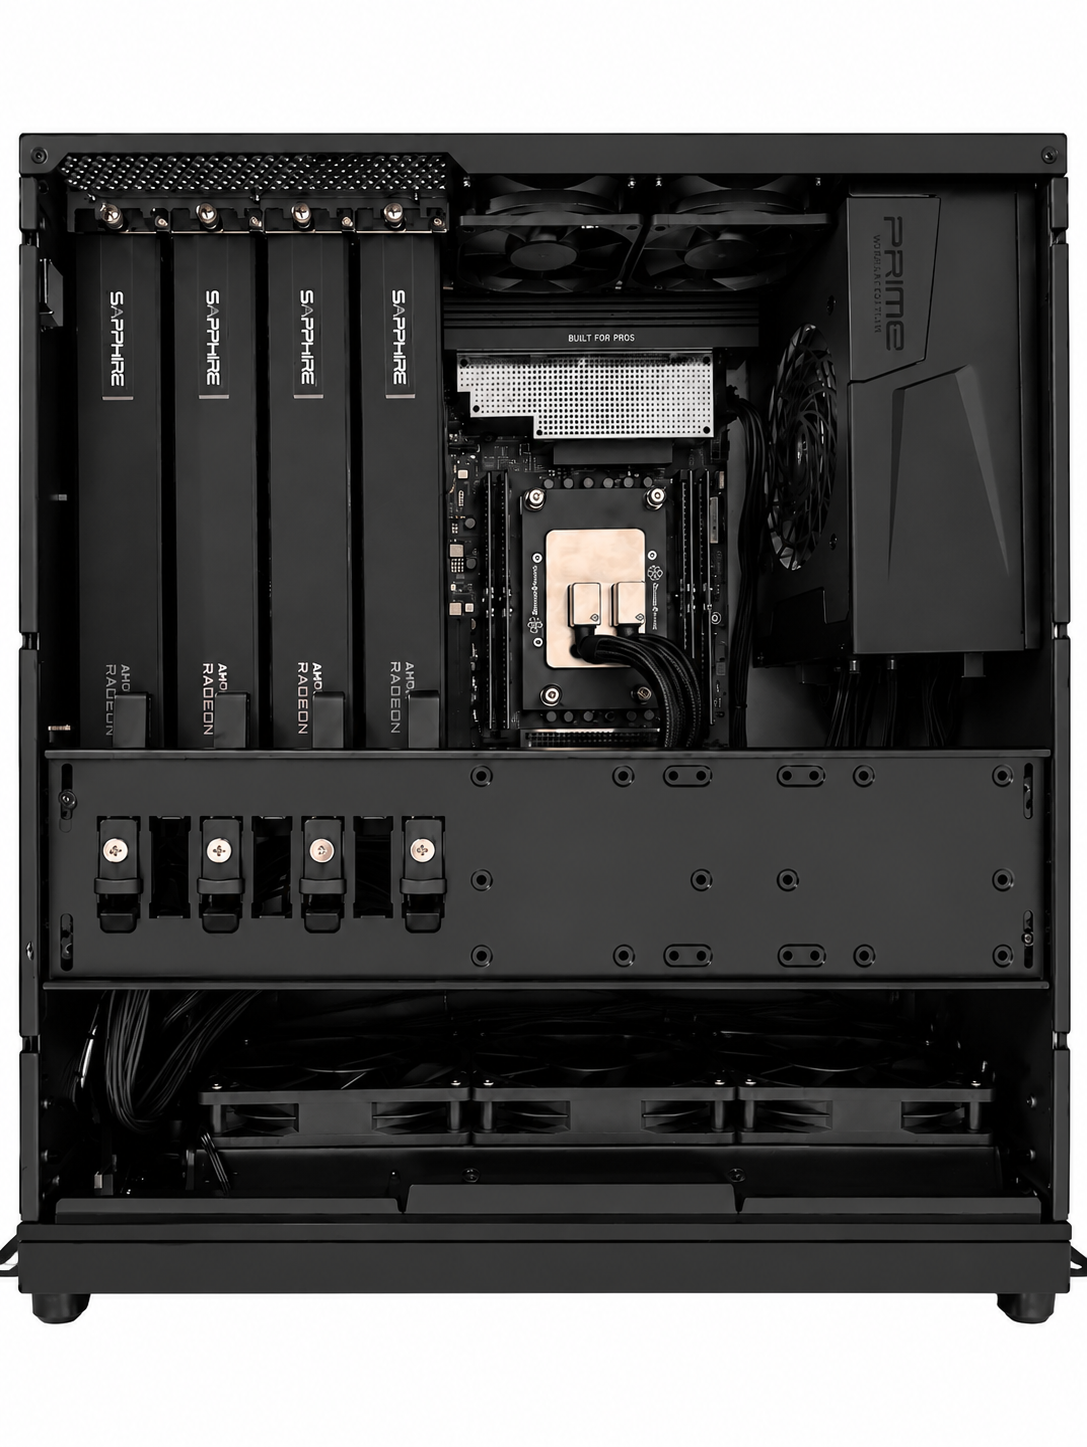
Holon Research
From $20,000 · 8 units left
Search case files and precedent
Draft contracts, letters, and motions
Search patient records and policies
Summarize long patient histories
Search your private codebase
Generate and refactor code
Search papers and internal data
Summarize studies and transcripts
Up to 120 tok/s per user.
No cloud or telemetry.
Runs on your LAN.
Major open models, kept current.
Accounts, queues, and serving included.
Outlet to first token.
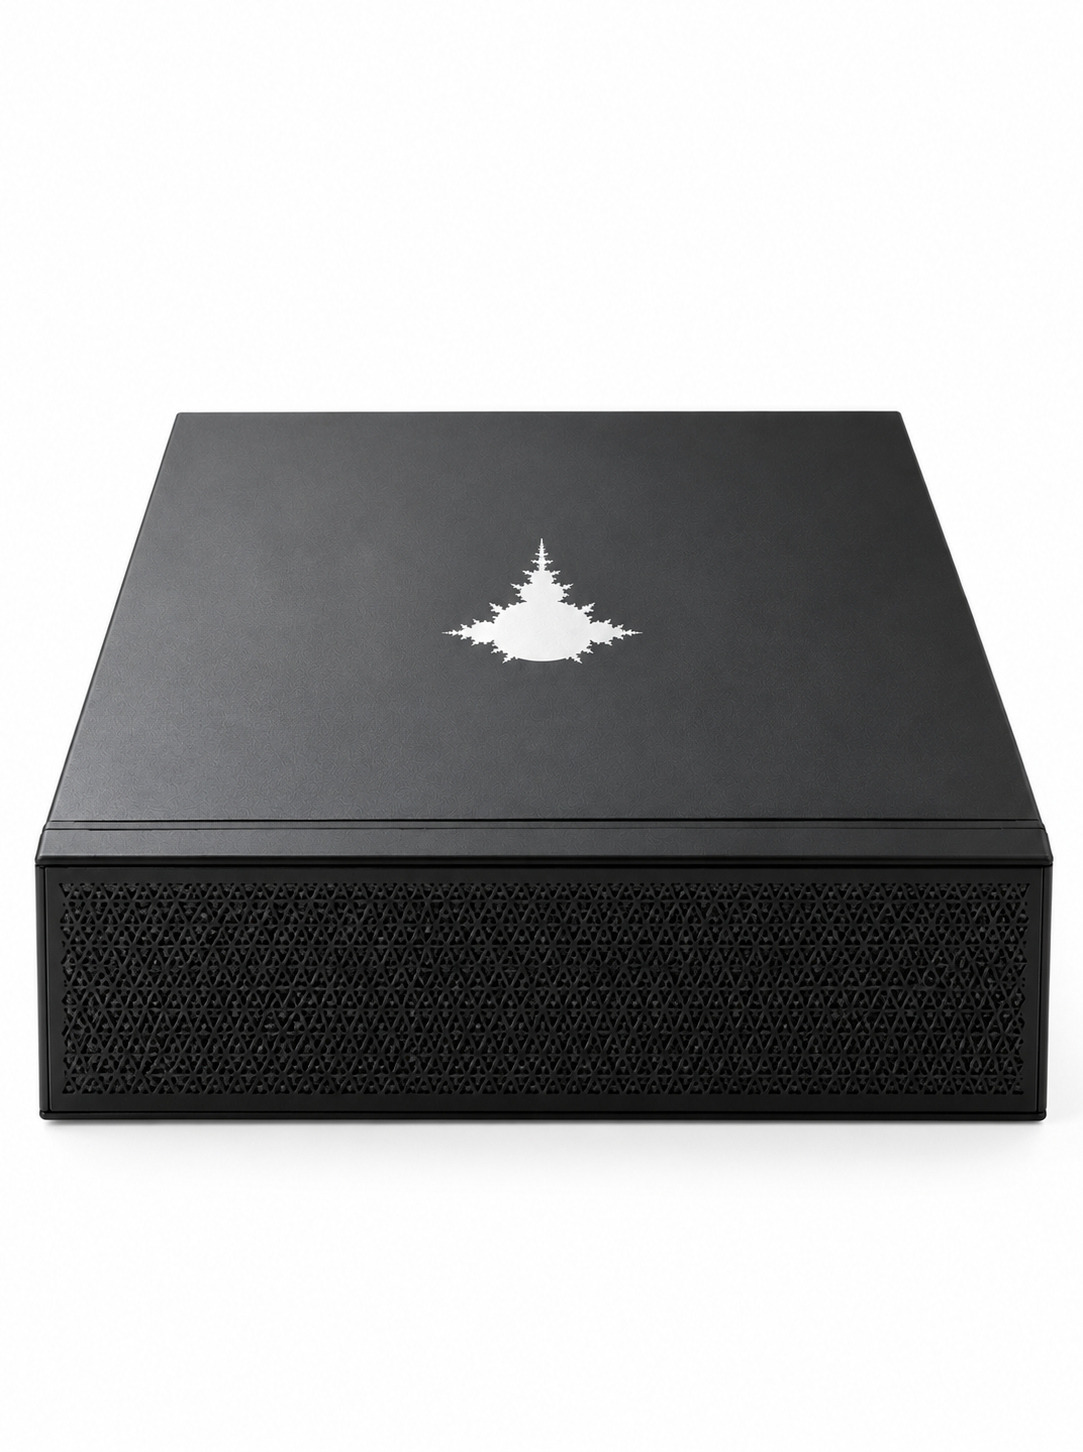
Up to 16 people can work at the same time, with response speeds designed to feel like cloud AI.
Based on Qwen3.8-27B MXFP4, 90/10 input/output split, 99% cache hit rate, and 60% utilization over 30 days.
Qwen3.8-27B
Aggregate decode throughput. Higher is better.
Holon and vLLM use the same checkpoint and hardware at C=8. RTX PRO 6000 uses the official FP8 checkpoint at C=8 with SGLang + DSpark and an 8K context. Mac Studio uses a published 8-stream MLX oQ8e result. The DGX figure is two times the published 55.8 tok/s C=10 FP8+MTP result. Cross-platform settings differ, so those rows are directional rather than matched laboratory tests. RTX PRO source · Mac source · DGX source
Matched settings: same Qwen3.8-27B-FP8 checkpoint, 4× R9700 at 210 W, TP=4, BF16 KV, C=8, 4,096-token prompts/user, 2,048 output tokens/user, MTP-3, two runs each.
| Model profile | Quant | KV type | Users | Prefill | Peak aggregate decode at 4K | Context window |
|---|---|---|---|---|---|---|
| Qwen3.8-27B MXFP4 | MXFP4 | BF16 | 16 | 9,830.96 tok/s | 1,426.02 tok/s | 131,072 tokens |
| Qwen3.8 Next Flash Int4/FP8 | Int4/FP8 | BF16 | 16 | 7,243 tok/s | 849 tok/s | 131,072 tokens |
| Qwen3.8-27B FP8 | FP8 | BF16 | 8 | 7,025 tok/s | 813.9 tok/s | 139,264 tokens |
| GLM 5.3 Flash | MXFP4 | FP8 | 4 | 4,094.78 tok/s | 113.33 tok/s | 128,000 tokens |
| DeepSeek V4.0 Flash 0731 | native | FP8 | 4 | 2,268 tok/s | 105.99 tok/s | 262,144 tokens |
Supported models
Uncensored / Abliterated
Need to deploy a custom model instead?
Reach outHolon runs inside your office. We cannot read your prompts, documents, or outputs.
Where data lives
Prompts, files, and outputs stay local.
Who can access it
Admins control users and model access.
Network access
Web access is optional and can be disabled.
A chat window, document upload, and web search. If your team can use a messaging app, they already know how to use this.
Monitor hardware, models, users in one place.
 Codex
 Pi
 OpenCode
OpenAI-compatible API.
Plugins for Codex, Pi, and OpenCode with one-click setup.
250,000 tok/s for document search.
Supports: pplx embed 0.6b
Use the included self-hosted tools or connect your own. Administrators can disable web access entirely.
If you can setup a coffee machine, you can setup a Holon.
Holon Research, Inc.
We build and support the hardware, model runtime, and local-first interface as one system. You speak with the people who built it, beginning with a guided deployment call.
Your quote states the warranty period, covered components, response target, and replacement process before you place an order.
We plan placement, network access, accounts, and first workflows with the person who manages technology in your office.
Your installed engine and models continue running locally without a subscription or a remote dependency on Holon Research.
Try before you buy
Request a remote session on a demo unit. Bring a representative, non-sensitive document or task and see the employee experience before discussing a deployment.
No. Every unit includes a guided setup call. We walk the person who manages your office technology through placement, local-network access, accounts, and the first workflow.
Your written quote states the warranty period, covered components, support hours, response target, and hardware replacement process before you place an order.
Yes. Use the quote form below or email [email protected] and tell us what your procurement process requires.
Ask us to include any available payment, financing, or leasing options in your quote. We will not represent a monthly option as approved until its terms are in writing.
A $1,000 deposit reserves a build slot. We then confirm the configuration, final balance, and ship window in writing. The remaining balance is invoiced before the unit ships.
Batch 1 currently ships within the United States. Your order shows shipping, applicable tax, deposit terms, and the return or cancellation policy before the remaining balance is due.
Yes. Air-gapped by default. The optional web search feature is admin-controlled and can be switched off entirely.
Your administrators choose the backup destination and retention policy. Holon Research does not copy your prompts, documents, or indexes to its own systems.
The engine and installed models run locally on hardware you own. There is no per-seat subscription that disables the unit when it expires.
Batch 1 price
8 units left in Batch 1 · 2 of 10 booked
Configuration and ship window confirmed after deposit ·
Try a unit before you buy
Buying through a PO or invoice? Email us and we'll send one the same day.
Talk to us
We will reply with the right configuration, deployment questions, and written commercial terms. Prefer a call? Include your number and the best time to reach you.